Welcome to Xianglong Yan’s (闫相龙) personal website!
I am currently a fourth-year undergraduate student at Shanghai Jiao Tong University (SJTU), majoring in Computer Science and Technology at the School of Computer Science, SJTU. I am advised by Prof. Yulun Zhang.
My research focuses on efficient large language model (LLM) deployment, with particular emphasis on model compression and long-context inference. I am especially interested in post-training quantization (PTQ), low-bit quantization (e.g., binarization and ternarization), and KV cache compression, aiming to build accurate yet resource-efficient LLM systems that are practical for real-world deployment.
I am always open to collaborations and academic discussions. Feel free to reach out via email at yanxianglong@sjtu.edu.cn, or connect with me on WeChat (ID: yxlsds).
🔥 News
- 2026.09: 🎉🎉 Our paper D²Quant has been accepted to NeurIPS 2026!
- 2026.09: 🎉🎉 I was awarded the SenseTime Scholarship (30 recipients nationwide each year)!
- 2026.03: 🎉🎉 We released Awesome Visual Autoregressive Modeling, a curated list of 60+ papers on the VAR paradigm!
- 2026.01: 🎉🎉 Our papers PT²-LLM and Quant-dLLM have been accepted to ICLR 2026!
- 2025.11: 🎉🎉 Our team was awarded the Grand Prize at the National “Challenge Cup” Competition (挑战杯全国特等奖)!
- 2025.01: 🎉🎉 Our paper ARB-LLM has been accepted to ICLR 2025!
📝 Publications
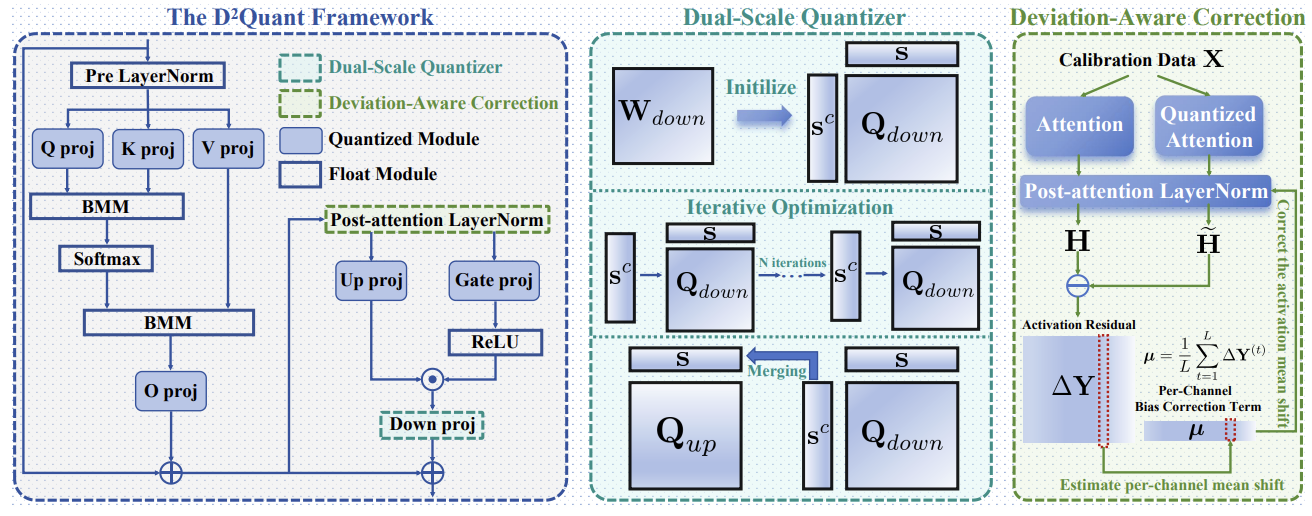
D²Quant: Accurate Low-bit Post-Training Weight Quantization for LLMs
Xianglong Yan†, Chengzhu Bao†, Zhiteng Li, Tianao Zhang, Shaoqiu Zhang, Ruobing Xie, Xingwu Sun, Yulun Zhang
- TL;DR: Dual-scale quantization and deviation-aware correction improve sub-4-bit weight-only post-training quantization for LLMs.
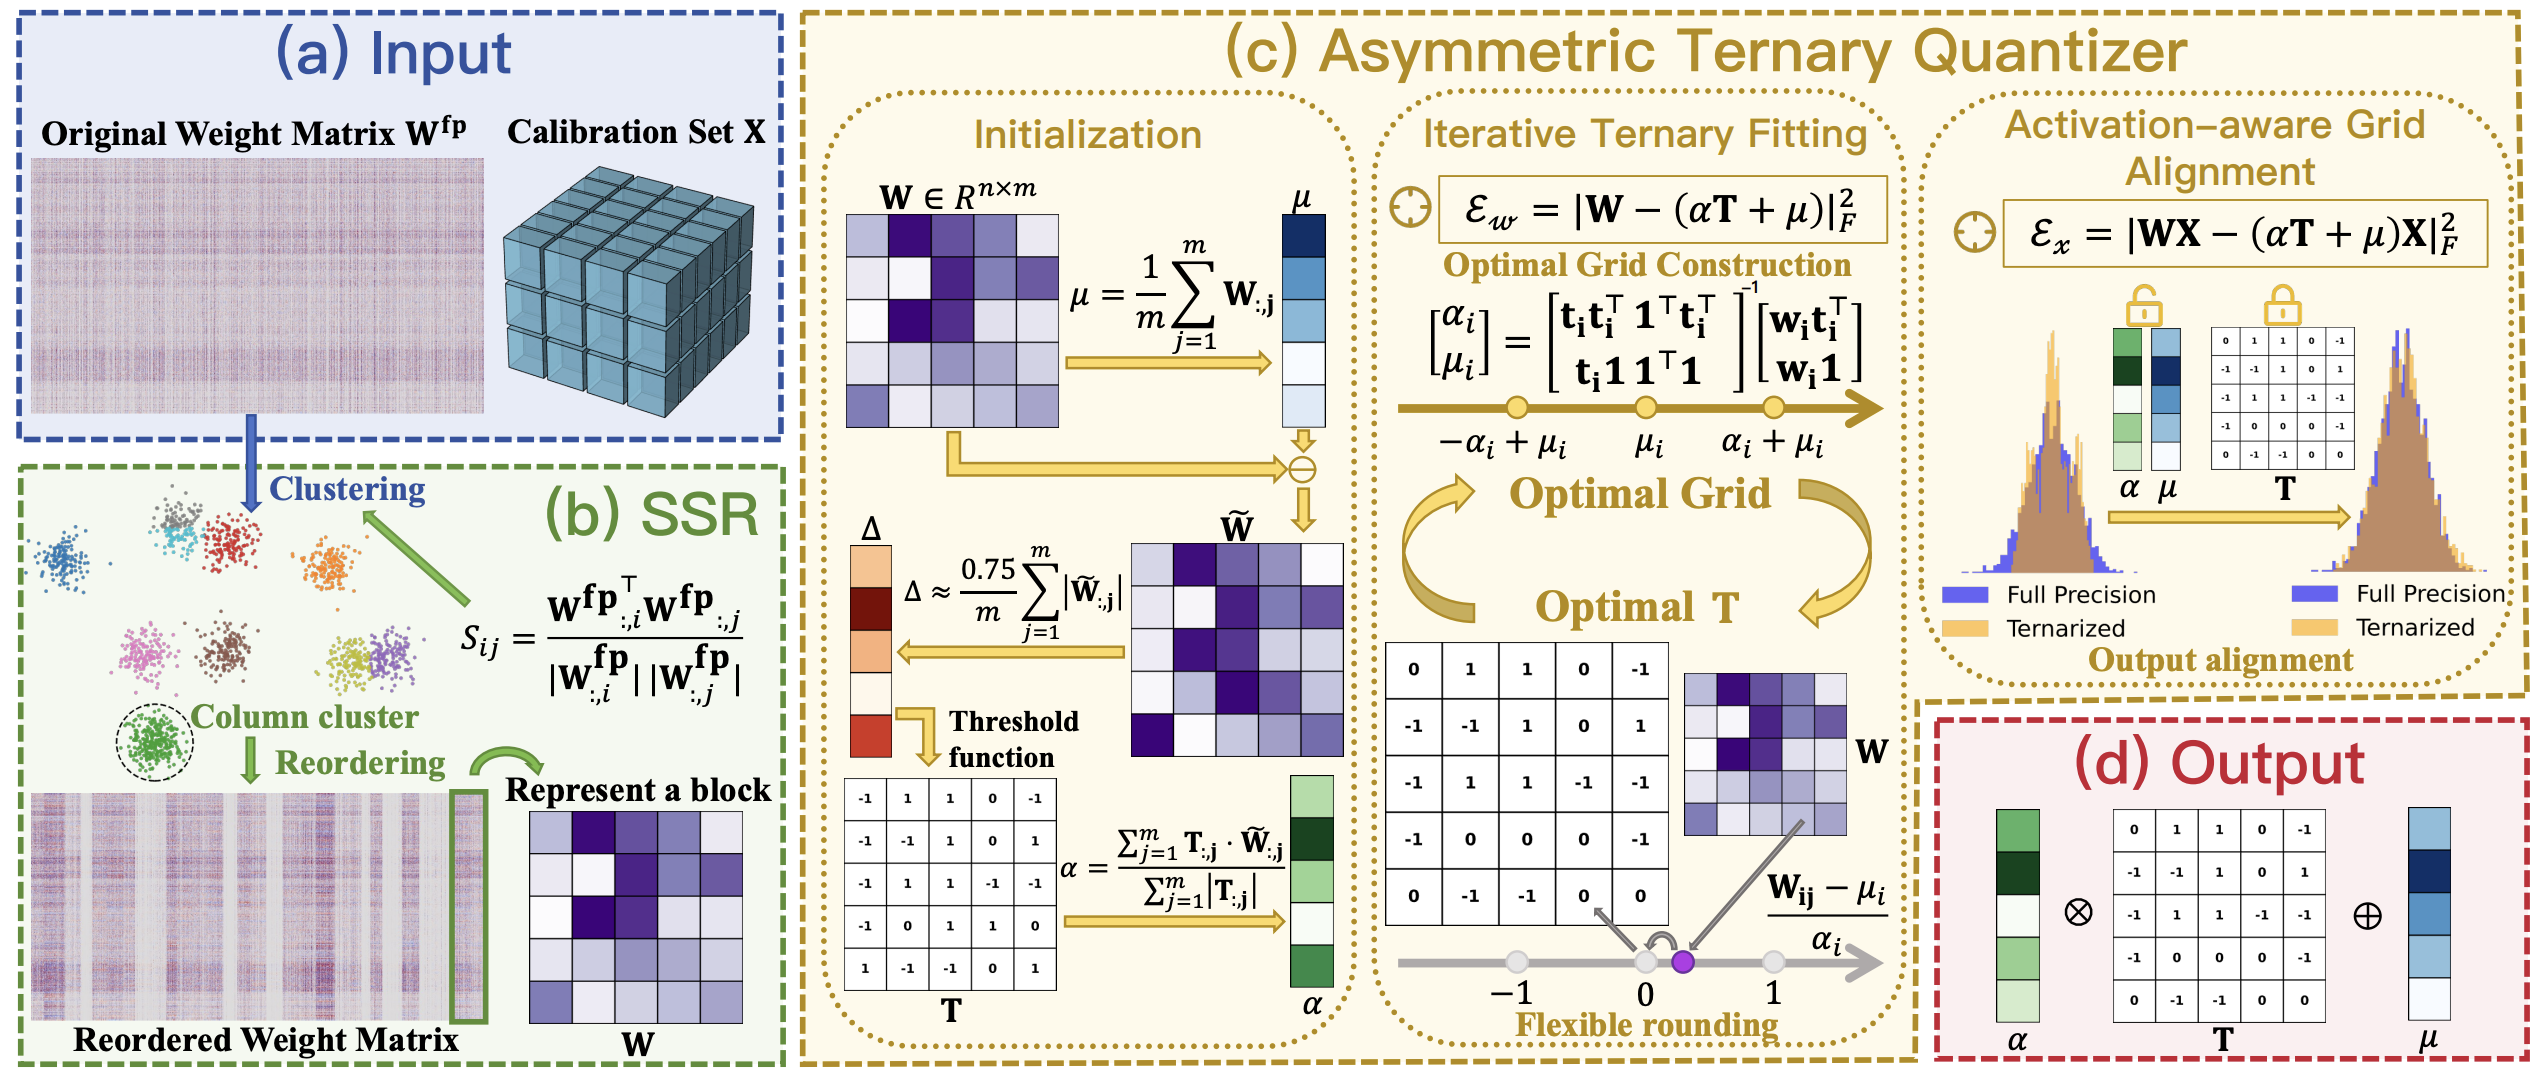
PT²-LLM: Post-Training Ternarization for Large Language Models
Xianglong Yan†, Chengzhu Bao†, Zhiteng Li, Tianao Zhang, Kaicheng Yang, Haotong Qin, Ruobing Xie, Xingwu Sun, Yulun Zhang*
- TL;DR: An efficient post-training ternarization framework for LLMs, incorporating an asymmetric ternary quantizer and column rearrangement strategy.
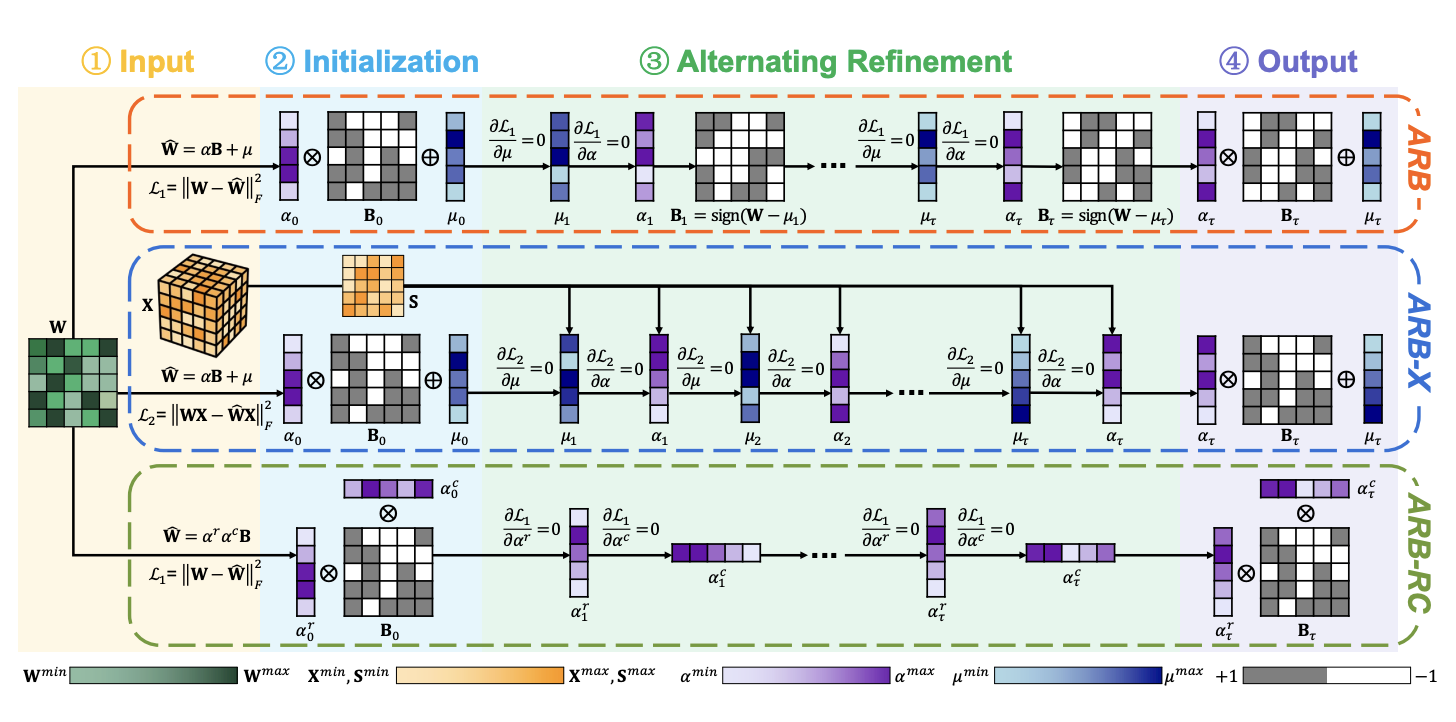
ARB-LLM: Alternating Refined Binarizations for Large Language Models
Zhiteng Li†, Xianglong Yan†, Tianao Zhang, Haotong Qin, Dong Xie, Jiang Tian, Zhongchao Shi, Linghe Kong*, Yulun Zhang*, Xiaokang Yang
- TL;DR: Proposes alternating refined binarization for LLMs, surpassing FP16 models on the Pareto curve.
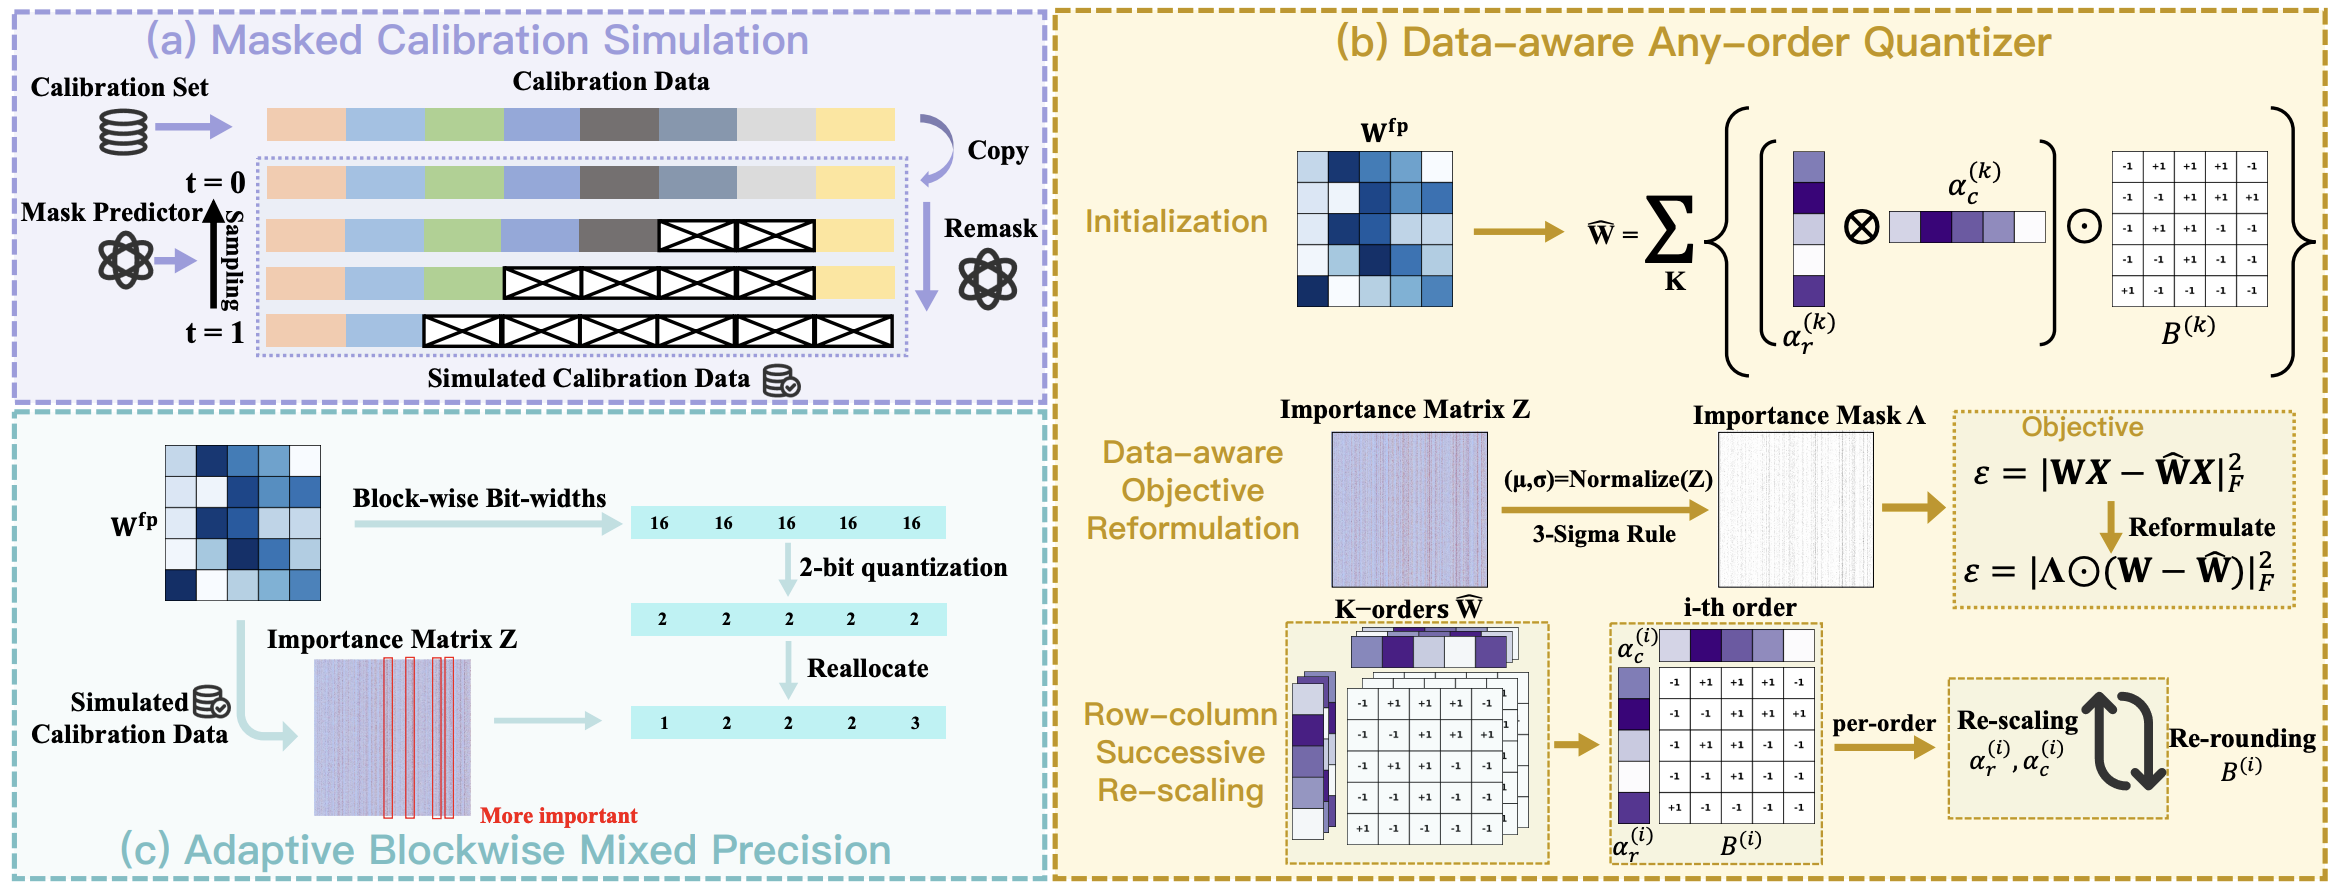
Quant-dLLM: Post-Training Extreme Low-Bit Quantization for Diffusion Large Language Models
Tianao Zhang†, Zhiteng Li†, Xianglong Yan, Haotong Qin, Yong Guo, Yulun Zhang*
- TL;DR: The first work to explore low-bit quantization for diffusion LLMs, achieving SOTA performance at 2-bit.
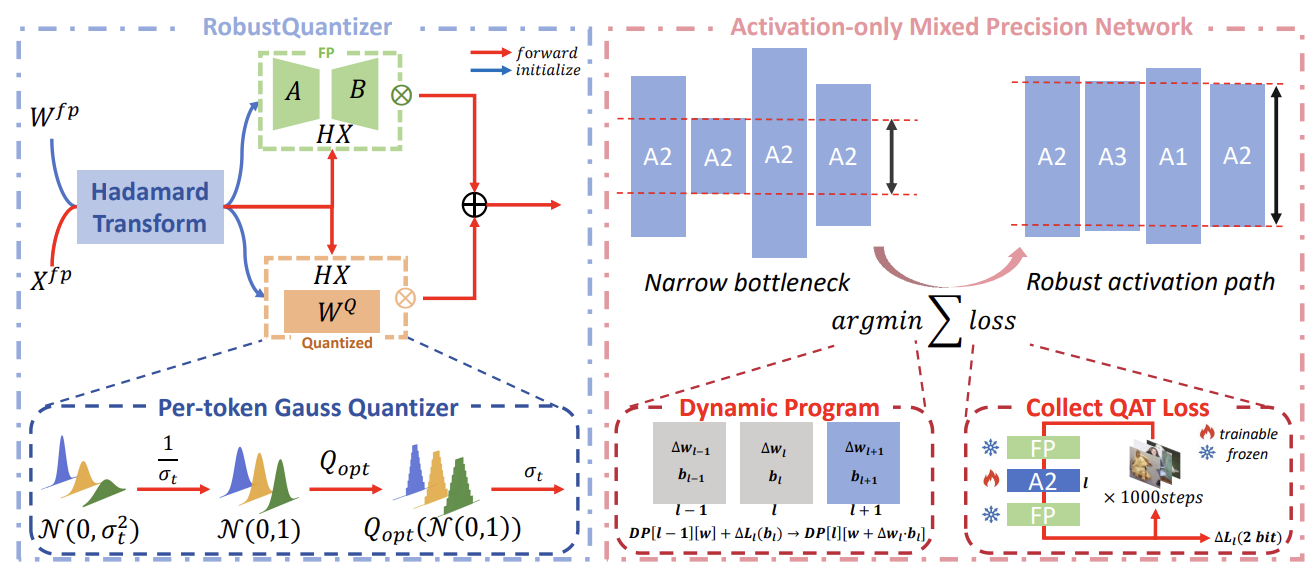
RobuQ: Pushing DiTs to W1.58A2 via Robust Activation Quantization
Kaicheng Yang, Xun Zhang, Haotong Qin, Yucheng Lin, Kaisen Yang, Xianglong Yan, Yulun Zhang
- TL;DR: Robust activation quantization and mixed precision enable diffusion transformers with ternary weights and near 2-bit activations.
CVPR 2026 Workshops
-
Zheng Chen, Kai Liu, Jingkai Wang, Xianglong Yan, et al. · Code
TL;DR: Summarizes the NTIRE 2026 ×4 image super-resolution challenge across restoration and perceptual tracks.
-
Kai Liu, Haoyang Yue, Zeli Lin, Zheng Chen, Jingkai Wang, Jue Gong, Jiatong Li, Xianglong Yan, et al. · Code
TL;DR: Benchmarks ×4 super-resolution for remote sensing infrared images and summarizes participating methods.
🎖 Honors and Awards
- 2024.10: National Scholarship, China (Top 0.2%)
- 2026.09: SenseTime Scholarship (30 recipients nationwide each year)
- 2025.09: NSFC Undergraduate Young Scientist Research Grant
- 2025.11: National Grand Prize, “Challenge Cup” Competition (Team Leader)
- 2025.12: SJTU Model Student (Top 10 university-wide, 2025)
💼 Internships
- 2026.03 - 2026.09, Intern, Model Acceleration Group, Hunyuan.
📖 Educations
- 2023.09 - now, B.Eng. in Computer Science and Technology, Shanghai Jiao Tong University (SJTU), Shanghai, China.
- 2020.09 - 2023.06, High School, The Experimental High School Attached to Beijing Normal University, Beijing, China.
🤝 Academic Service
- Reviewer, ICLR 2026
- Reviewer, NeurIPS 2026
- Reviewer, ICLR 2027